BISINDO Gesture Recognition Generalization
Improving the generalization of BISINDO gesture recognition through realistic 3D keypoint augmentation.
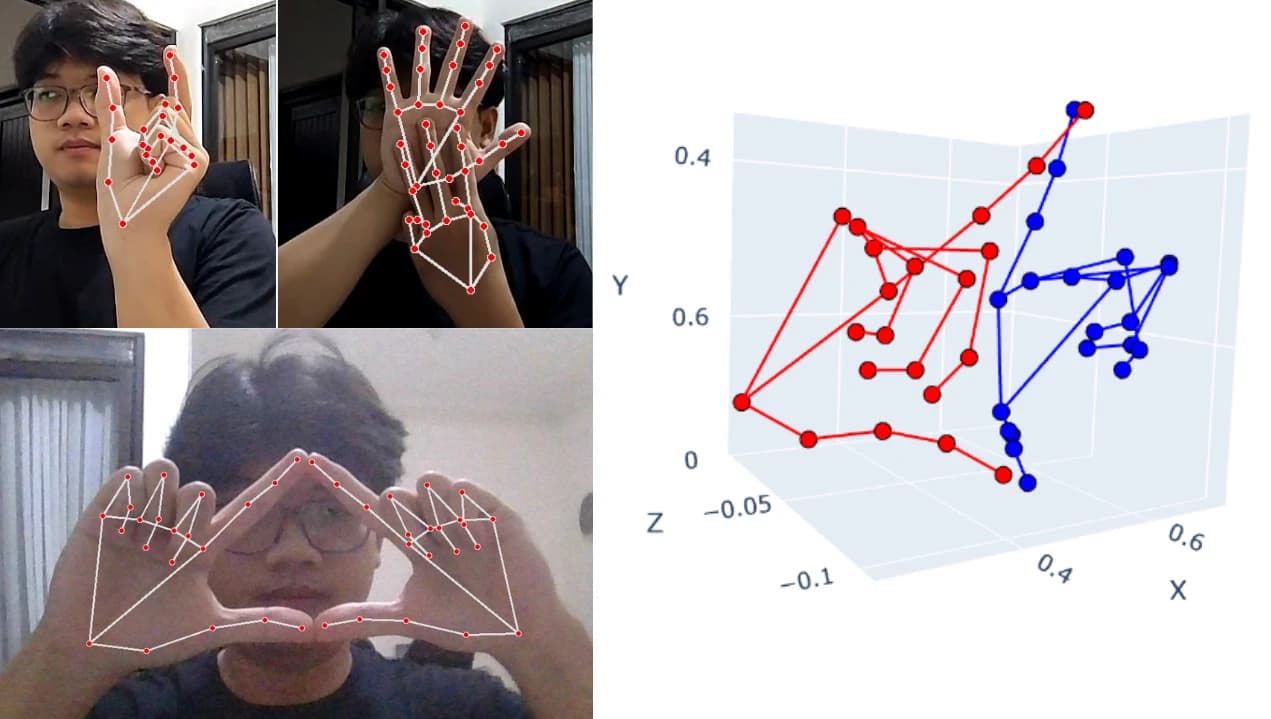
Overview
Designed and developed a machine learning pipeline to improve the cross-domain generalization of BISINDO alphabet recognition by introducing scenario-based 3D keypoint augmentation using MediaPipe hand landmarks.
Problem
Gesture recognition models trained on a single subject often achieve excellent evaluation scores on internal datasets but fail to generalize to new users, devices, and real-world environments due to overfitting.
Solution
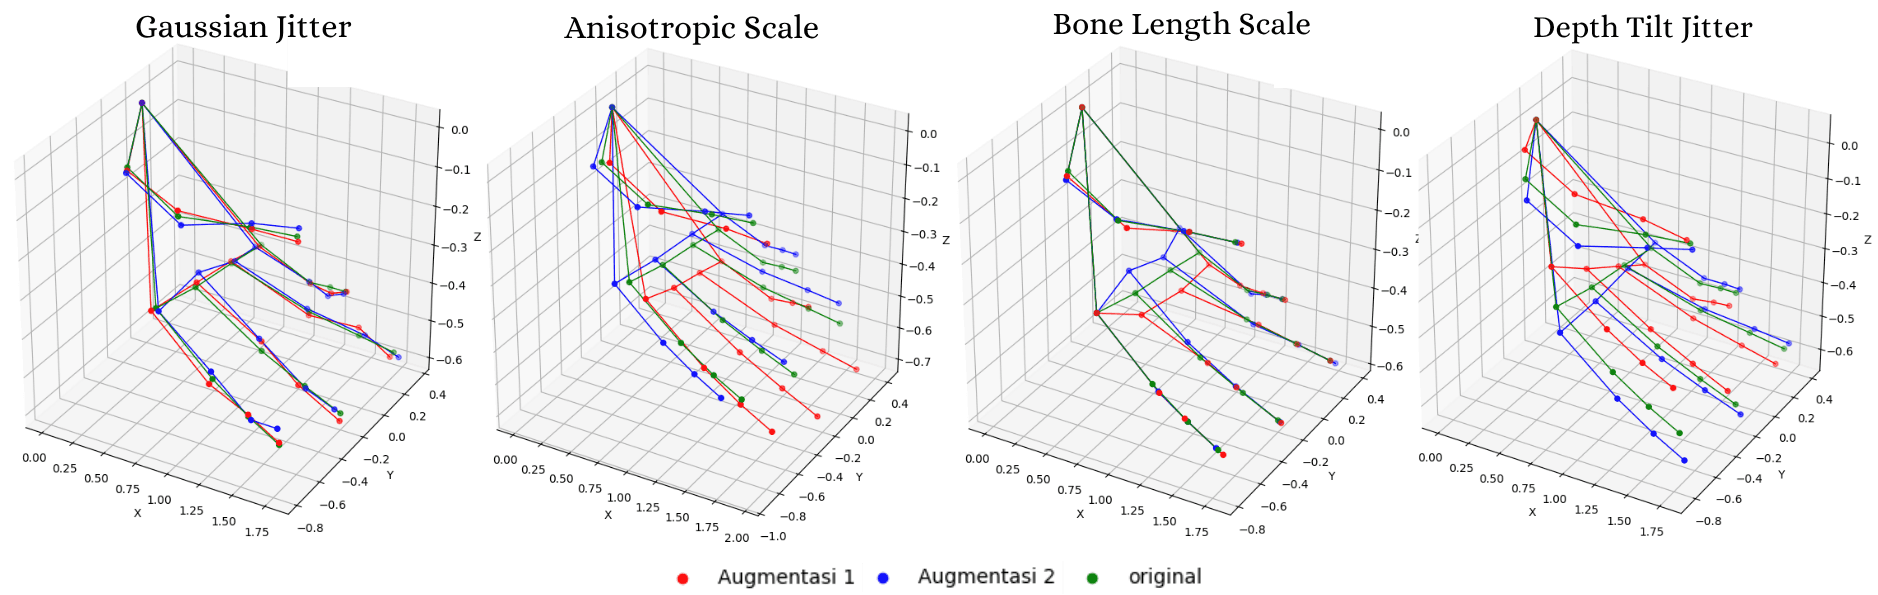
Proposed a realistic 3D keypoint augmentation framework that simulates natural hand variations before training an MLP classifier. The pipeline includes landmark normalization, feature engineering, augmentation, model training, and cross-domain evaluation.
Architecture
Engineering Decisions
- Used MediaPipe 3D hand landmarks instead of raw images to reduce computational complexity while preserving gesture semantics.
- Designed realistic augmentation strategies based on natural hand movement rather than random perturbations.
- Implemented wrist-centered normalization and scale normalization to improve robustness across users.
- Evaluated the model using an external dataset to measure real-world generalization instead of relying solely on internal validation.
Challenges
- Designing augmentation strategies that introduce realistic variations without distorting gesture semantics.
- Preventing overfitting caused by single-subject training data.
- Maintaining stable training performance while increasing data diversity.
Lessons Learned
- Improving generalization is often more valuable than pursuing higher training accuracy.
- Carefully designed synthetic data can outperform simply collecting more data.
- External evaluation is essential for validating real-world machine learning performance.
Future Improvements
- Evaluate on larger multi-subject datasets.
- Explore Graph Neural Networks for hand landmark representation.
- Investigate Transformer-based sequence modeling for gesture recognition.
- Extend the system to real-time sentence-level BISINDO recognition.
Technology
Gallery
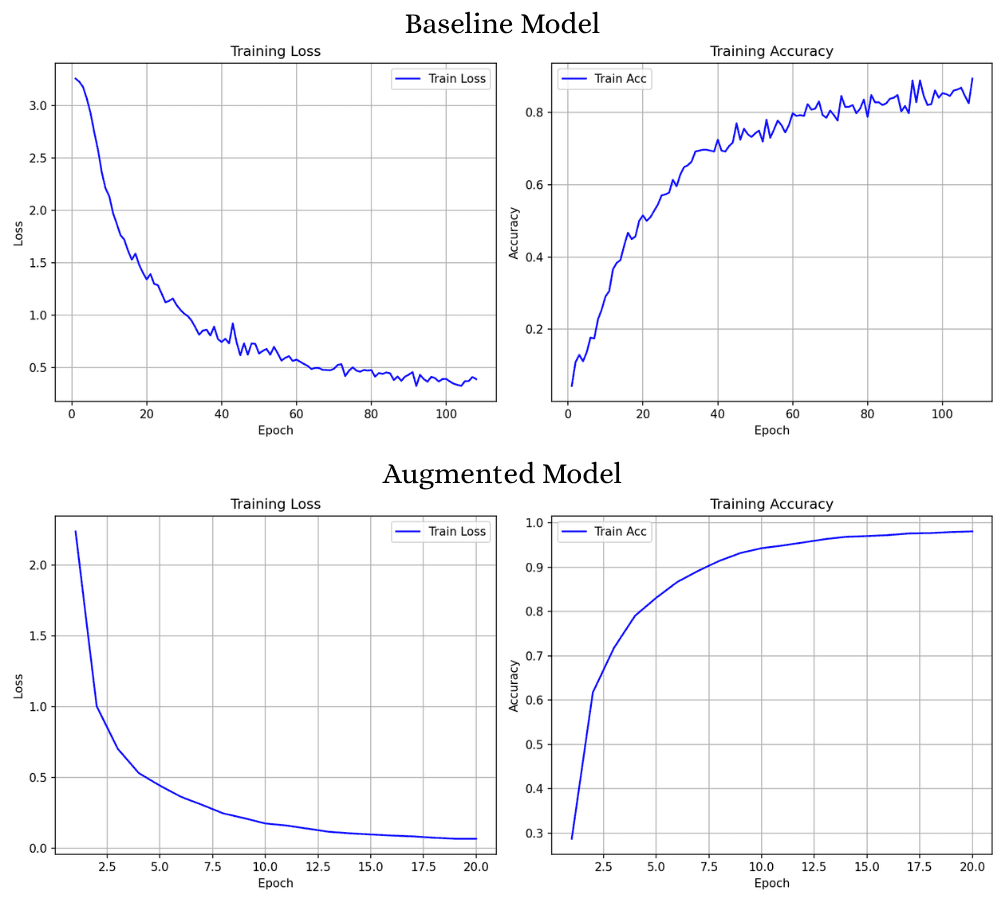
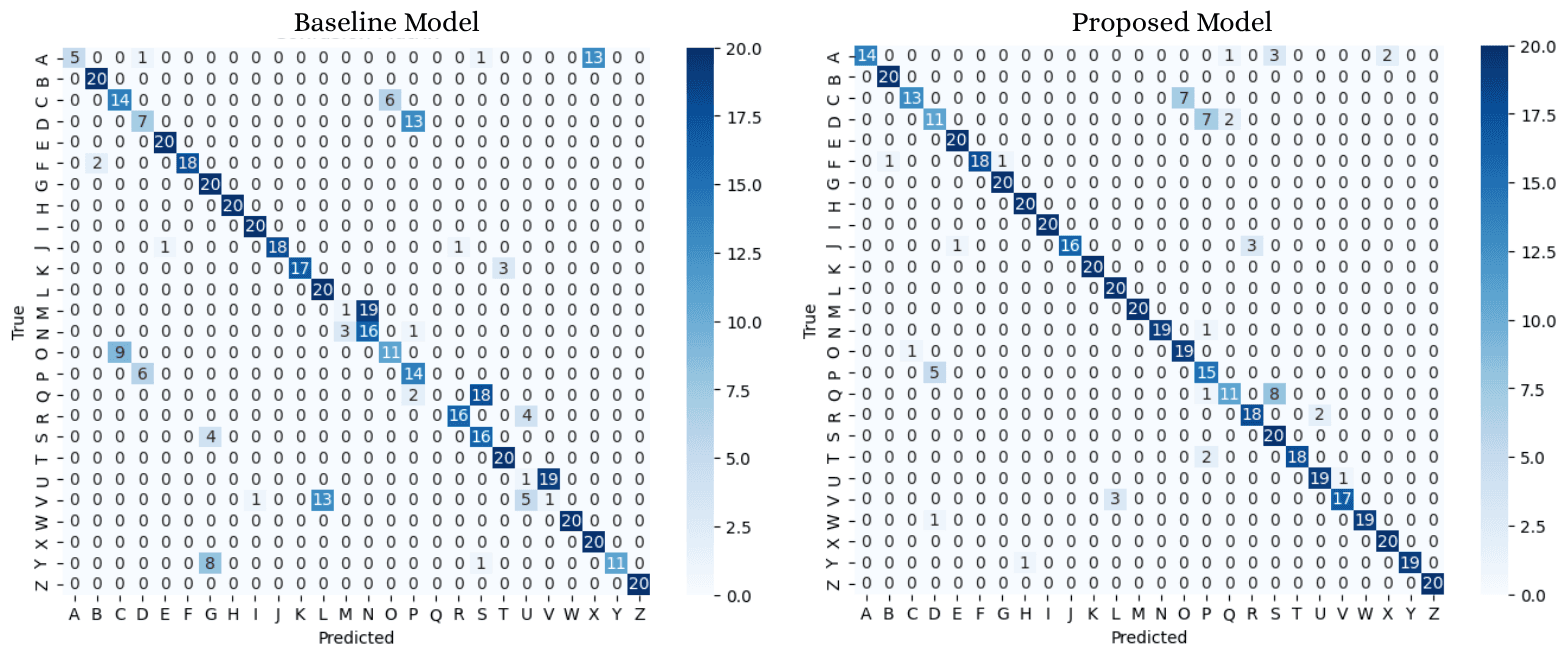
Results
Dataset
Single-subject training dataset + external cross-domain evaluation dataset